A trace records steps in a process. Keep each claim connected to its source.
Read the research question.
Locate the relevant figure or example.
Keep source links with your notes.
Record open questions for the next pass.
3. Keep code intact
for paper in reading_list:
    print(paper["title"], paper["url"])
Illustrative reading checklist. Open each source for the complete paper.
# Three papers. Three research questions.

> **Sources:** [When Agents Slow Down](https://arxiv.org/abs/2609.15309) · [WearableQA](https://arxiv.org/abs/2609.05405) · [Conversation Compiler](https://arxiv.org/abs/2603.29678)

## 1. Start with the research question

1. **Agent reasoning**
   - Inspect the test-time strategy and token budget.
   - Follow the decisions recorded in the *trace*.
2. **Wearable data**
   - Check the available health signals.
   - Separate the task definition from the evidence.
3. **Conversation analysis**
   - Follow the views used to inspect an agent trace.
   - Return to the original paper for its full method.

### 1.1 A compact comparison

| Paper | Research focus | Read for |
| :--- | :--- | :--- |
| [When Agents Slow Down](https://arxiv.org/abs/2609.15309) | LLM agent strategies | Compute and progress |
| [WearableQA](https://arxiv.org/abs/2609.05405) | Reasoning over wearable data | Signals and questions |
| [Conversation Compiler](https://arxiv.org/abs/2603.29678) | Agent trace analysis | Views and evidence |

## 2. Trace the evidence

A **trace** records steps in a process. Keep each claim connected to its source.

- Read the research question.
  - Locate the relevant figure or example.
  - Keep source links with your notes.
- Record open questions for the next pass.

## 3. Keep code intact

```python
for paper in reading_list:
    print(paper["title"], paper["url"])
```

Illustrative reading checklist. Open each source for the complete paper.
Translation Original structure preservedSimplified Chinese
for paper in reading_list:
    print(paper["title"], paper["url"])
此处为阅读清单示例;完整内容请查阅各篇原文。
Aa
Your preferred termtrace →
Keep your terminology consistent with the domain and context.
Localized interface preview · Swipe to explore. Papers and scores use public metadata.
PAPER RADAR / MULTIDIMENSIONAL SCORING
Ranking evidence and preferences
Scores combine topic matching, source evidence for authors and institutions, publication age and your research interests. Inspect the contributing evidence when deciding what to read.
Combine relevance, author and institutional evidence, and recency through layered weighting.
02
Inspect the evidence
Explore scores, author contributions and source records.
03
Stay with the paper
View annotations on arXiv and save papers for your next read.
PAPER RADAR / SELECTED EXPERIMENTS
Research behind the tool
Measurements on a snapshot of 174,640 acquired records inform two choices in Paper Radar: keep abstracts with their sources, and reuse the source graph when reading priorities change.
Coverage from abstracts
64.5%
Of the focused topic-matched cohort, 37,495 of 58,094 papers had no matching title signal.
Faster response preparation with a retained source graph, for 1,000 returned papers per request.
Elapsed response time (s) · six directions · three paired runs per direction
Populations and measurement conditions
Library. The acquisition through 3 November 2026 contains 174,640 unique in-scope paper identifiers, with versions and cross-listings merged.
Coverage. The same direction definitions admit 20,599 papers from titles and 58,094 from titles plus cached abstracts. The 64.5% is calculated within this focused cohort.
Retrieval. The external CSFCube benchmark contains 34 distinct query papers across 50 query–facet tasks. The model, prompts and candidate pools stay fixed; expert grades are withheld from scoring. This evaluates the information supplied to a fixed relevance scorer.
Preparation. Mean fresh-source times span 151.04–168.27 seconds; retained-graph times span 41.77–55.47 seconds. Ratios compare unrounded means within each direction. All 18 matched pairs return identical scores and source bindings; the target direction is uncached in both modes.
Preparation timing covers the native response call through complete serialization from loaded inputs, on an Intel Xeon Platinum 8369B CPU host with 800 GiB memory and Node.js v26.4.0. Initial loading and worker setup are excluded. These timings apply to retained state in a persistent local service; independent CLI processes prepare their own contexts.
Inspect in the browser. Reuse through the CLI.
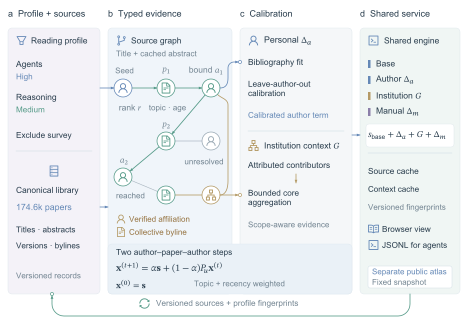
The browser makes the reading list and its supporting evidence inspectable. A local command-line interface returns JSON or JSONL with source identifiers, abstracts, score components and missing-evidence states for downstream tools.
System view: from a reading profile to shared evidence
Source and context caches support the browser and structured agent outputs. The public atlas retains a separate fixed snapshot. Open the full diagram ↗
PAPER RADAR / LOCAL CLI
Use paper evidence in your own tools
Rank supplied metadata and export JSONL for a reading assistant, retrieval pipeline or research agent. The toolkit requires Node.js 22.13 or newer, with no npm installation. It is separate from the Chrome extension.
201 KB · Offline ranking + JSONL conversion · No model key required
Extract the ZIP and open a terminal in its knowme-cli-1.2.7 folder. The included three-paper example is synthetic interface data, not a research result.
JSONL begins with a manifest, followed by paper records using schema knowme-ranked-evidence-v1. Installing the Chrome extension does not install these terminal commands. Graph export and citation refresh are not included in this download.
Use your own records, profile or stdin
Replace the synthetic example with {"records":[{"paper":{...}}]}. Each paper carries its ID, title, abstract in summary, author list, dates and categories. Supply your complete relevant bibliography: the date window selects candidates while context uses all supplied records.
Use --profile profile.json with {"name":"My research","topics":{"rag":1,"reasoning":2}}, or use --topics rag:1,reasoning:2 instead. Priority 1 is highest and 4 is lowest. --exclude matches literal title/abstract text and can be repeated.
--input - accepts the same JSON via stdin. Check the process exit status, parse stdout and retain stderr for diagnostics. Keep the returned snapshotId with downstream documents. The ZIP's README contains the complete flag and output reference.
The extracted package was checked with Node.js v26.4.0 using the included synthetic input. File, stdin and inline-topic results matched the current source implementation at the same clock; the check made no network or database calls. The package manifest lists its files and source provenance.
Read the score with its evidence
Scores express reading priority under the selected profile and supplied records. Inspect the abstracts and supporting sources to decide how a paper informs your research.
Each fresh CLI process prepares its own context. The retained-graph speedup above applies to a persistent local service; a small output limit does not remove preparation work.
GET STARTED
Start here.
Install. Set up. Start reading. Find answers as you go.
1
Install from the storePin Paper Radar to the toolbar for easy access.
2
Choose your interestsStart with 1–3 topics and run an online refresh.
3
Inspect and saveExplore scores and author evidence, then save papers worth reading.
How do I build my first paper cache?+
Choose your topics and run an online refresh. Then use cache-only mode to revisit the same date range and filters. Cache-only mode does not contact arXiv; refresh online for the latest papers.
How do I set up page annotations?+
Author profiles and Scholar search / arXiv details have separate controls. Compact mode keeps the KnowMe button and hides long status text and author coloring. Annotations use local records and a limited bundled index; a missing match does not imply a paper is unimportant.
Does my data sync automatically?+
Saved papers, cache, personal terms and history stay in the current browser and do not sync through your Google account. Export a backup before changing devices, browser profiles or uninstalling. Your chosen model service processes translations and connection tests.
Public store version checked on 2026-11-18: 1.2.6. The store controls extension availability; the CLI download is separate. Interface examples keep their recorded versions and scores.
 KnowMe · Research tools